


TL;DR
Typed decision models (TDMs) like TypeSafe Jev and GPT-6 Luna Decisions offer a fast, structured, and cost-effective alternative to chat-based LLMs for transportation tasks. While they can rival reinforcement learning in "zero-shot" traffic signal control, their predictive accuracy in travel choice currently lags behind traditional statistical models and requires meticulous input engineering to be effective.
What Problem Does This Paper Address?
Transportation systems rely on constant decision-making, from a traveler picking a commute mode to a traffic light timing its green phases. Traditionally, we solve these using Discrete Choice Models (like Multinomial Logit) or Reinforcement Learning (RL). However, these require massive amounts of behavioral data or thousands of simulation hours to calibrate.
Large Language Models (LLMs) offer a "zero-shot" alternative—they can make decisions based on natural language descriptions without specific training. But standard chat-based LLMs are slow, expensive, and prone to formatting errors when you need a machine-readable answer. This paper investigates Typed Decision Models (TDMs): a new class of models that combine LLM reasoning with a structured interface, returning specific actions and probabilities instead of long-winded text.
Methods
The authors systematically benchmarked two TDMs—TypeSafe Jev 1.14 and GPT-6 Luna Decisions—against a suite of baselines:
- Traditional: Multinomial Logit (MNL) for travel choice; MaxPressure and Greedy-queue for signal control.
- Learning-based: Proximal Policy Optimization (PPO), a standard RL algorithm.
- Chat LLMs: DeepSeek V4.1 Flash, GLM 5.3 Flash, GPT-6 Luna (chat version), and Claude Haiku 5.5.
The evaluation covered two distinct tasks:
- Travel Mode Choice: Predicting which mode (Train, Swissmetro, or Car) a human would choose based on trip attributes.
- Traffic Signal Control: A sequential task where the model must repeatedly select the best signal phase to minimize vehicle waiting time in a closed-loop simulation.
Datasets
- Swissmetro Dataset: A classic stated-preference survey dataset containing 1,791 choice records. It includes variables like travel time, cost, and headway.
- SUMO (Simulation of Urban MObility): Used for the traffic signal control task across four scenarios of increasing complexity: a simple 4-way intersection (2way), a real-world single intersection (cologne1), a 2x2 grid (2x2), and a multi-intersection corridor (cologne3).
Key Insights and Ideas
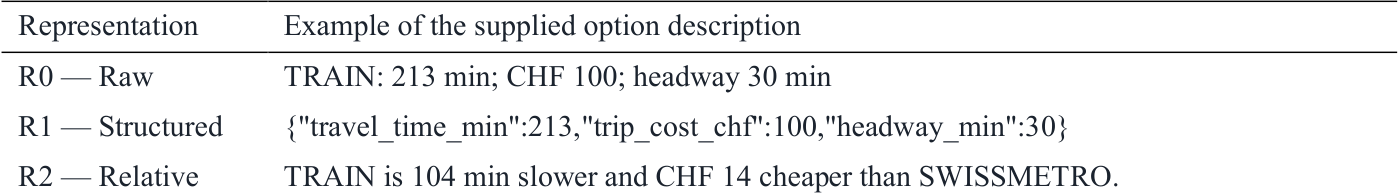
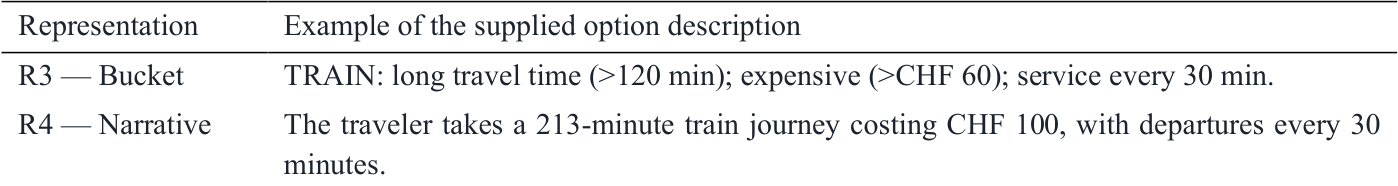
- Input Representation is Everything: The "Aha!" moment here is that TDMs are incredibly sensitive to how data is presented. Describing a train trip as a raw string (R0) vs. a structured JSON-like field (R1) vs. a relative comparison (R2) led to accuracy swings of up to 38 percentage points.
- The "Zero-Shot" Advantage: In traffic signal control, TDMs achieved competitive performance without any task-specific training. This is a huge win compared to RL models (like PPO) that require tens of thousands of simulation steps to learn a policy.
- Efficiency Gains: TDMs are significantly faster and cheaper than their chat-based counterparts. By skipping the text-generation phase, they reduce latency by roughly 50-70% and cut API costs by nearly half.
- Order Sensitivity: The models exhibited "position bias," where the order in which options were presented influenced the choice. Interestingly, this bias was less pronounced when the question was framed as "Which is best?" (normative) rather than "Which did they choose?" (predictive).
Key Results
- Accuracy Gap: In travel choice, the traditional MNL model remained the king with 0.688 accuracy. The best chat LLM (DeepSeek) hit 0.635, while the best TDM (Jev) reached 0.546 under standard settings. However, with optimized "Relative" representation and "Normative" framing, TDMs reached ~0.64 accuracy.
- Signal Control Success: In the simple
2wayscenario, Jev achieved a mean waiting time of 3.65s, actually outperforming the trained PPO model (4.16s) and traditional MaxPressure (6.00s). - Latency & Cost: Jev demonstrated a median latency of ~380ms and a cost of $0.069 per 1,000 decisions, making it the most efficient model tested. For comparison, chat-based models like Claude Haiku had latencies over 1.2s.
Limitations and Future Work
The paper notes that TDMs struggle as network complexity increases; in the cologne3 multi-intersection scenario, performance degraded significantly, suggesting that these models currently lack the "global" coordination needed for large-scale traffic management.
Future research directions include:
- Expanding evaluation to more diverse behavioral datasets beyond Swissmetro.
- Developing explicit coordination mechanisms for TDMs in multi-intersection networks.
- Exploring more complex transportation tasks like route selection and autonomous vehicle maneuvering.
Summary updated